Qwen 3.5 0.8B was fast, tiny, and a terrible code reviewer
Engine/model: Ollama, qwen3.5:0.8b-mlx
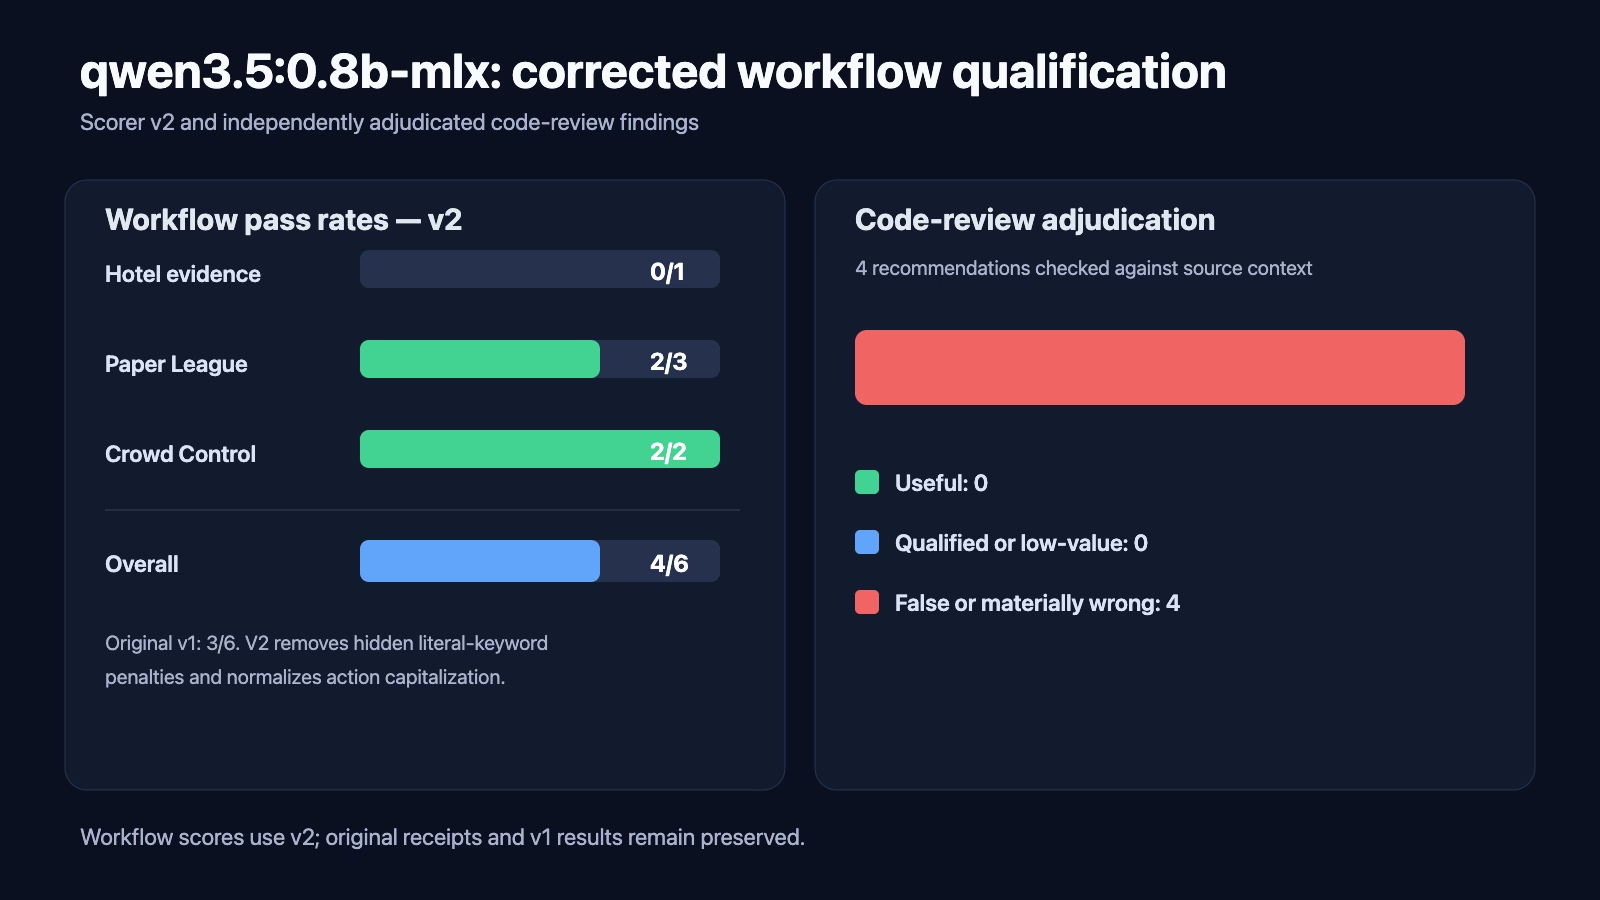
A 0.8B model has an obvious appeal: it is small enough to keep around almost for free and quick enough to answer before a larger model has properly warmed up. This run found that appeal, then found the limit. Qwen 3.5 0.8B passed three of six bounded cases, but every repository recommendation was false or materially wrong.
Methodology correction: This article originally reported 3/6 under scorer v1. Cloud controls exposed two benchmark defects: a hidden literal-keyword requirement and case-sensitive action enums. Under versioned scorer v2, this model scores 4/6. This supersedes the earlier workflow total; original receipts remain preserved, and the code-review adjudication and verdict are unchanged.
Budget correction — this supersedes the review-quality claim above. A later audit of the frozen suite found that non-hotel cases were capped at 320 output tokens and repository reviews at 3200. Two of this model’s four review calls hit that ceiling and returned output that could not be parsed at all; only two produced findings, and those two were adjudicated false or materially wrong. The earlier statement that all four reviews were false or materially wrong conflated two unparseable responses with two genuinely incorrect ones. Unparseable output is not evidence of bad judgment, and it must not be scored as such. The provisional verdict is therefore changed from deletion candidate to retest required, and this 1.16 GiB tag stays protected from deletion. A re-run at a raised output budget is in flight; this article will be updated with its result.
Fast, but not contract-safe
The workflow score was 3/6: hotel evidence 0/1, paper league 2/3, and crowd control 1/2. The hotel response contained five valid claims but also altered a quotation, which is enough to fail a literal-evidence job. One community reply missed the requested stance. The final portfolio case returned the wrong action and left required fields unusable.
The six short calls took 11.9 seconds in total, with a 0.90-second median. That speed is real. So is the cleanup bill.
Two reviews parsed and were wrong; two never parsed at all
Correction. Two of the four review calls never produced parseable output — both hit the 3200-token review ceiling and returned nothing that could be evaluated, so they are recorded as unscored, not as wrong. The two that did parse failed the deterministic validator, and independent inspection of the pinned source found no useful recommendation and no merely qualified one in either.
The mistakes in the two scored reviews were not subtle. One finding invented dynamic pricing work from a form that already stores the entered cost. Another called a parameterized database insert an injection flaw. A third proposed a nonsensical TypeScript entry-point fix. The last treated an explicitly documented local-development authentication default as an accidental production exposure.
Across all ten calls, the model processed 92,766 recorded tokens in 52.8 seconds. Repository packets accounted for most of the input. The model stayed concise, but brevity did not make the recommendations safer.
Provisional verdict: retest required — superseded, see correction above
Superseded. The preliminary label deletion_candidate was set before the budget audit; it is replaced by retest_required. For the record, the original reasoning was that the label is not deleted. At 1.16 GiB, the storage savings are modest, yet the campaign was looking for a trustworthy narrow role rather than a tiny model at any cost. This run did not find one. It may still be fine for disposable transformations with exact validators, but larger small models already compete for that job with fewer ways to go wrong.