Llama 3.3 70B passed the small jobs, then the review lane collapsed
Engine/model: oMLX, Llama-3.3-70B-Instruct-4bit
The 70B model opened well. It passed four of six bounded workflow cases, including the evidence-heavy extraction test, and handled two structured portfolio actions correctly. Then the repository-review stage fell apart: three calls failed at the request layer, and the one response that arrived was not valid JSON.
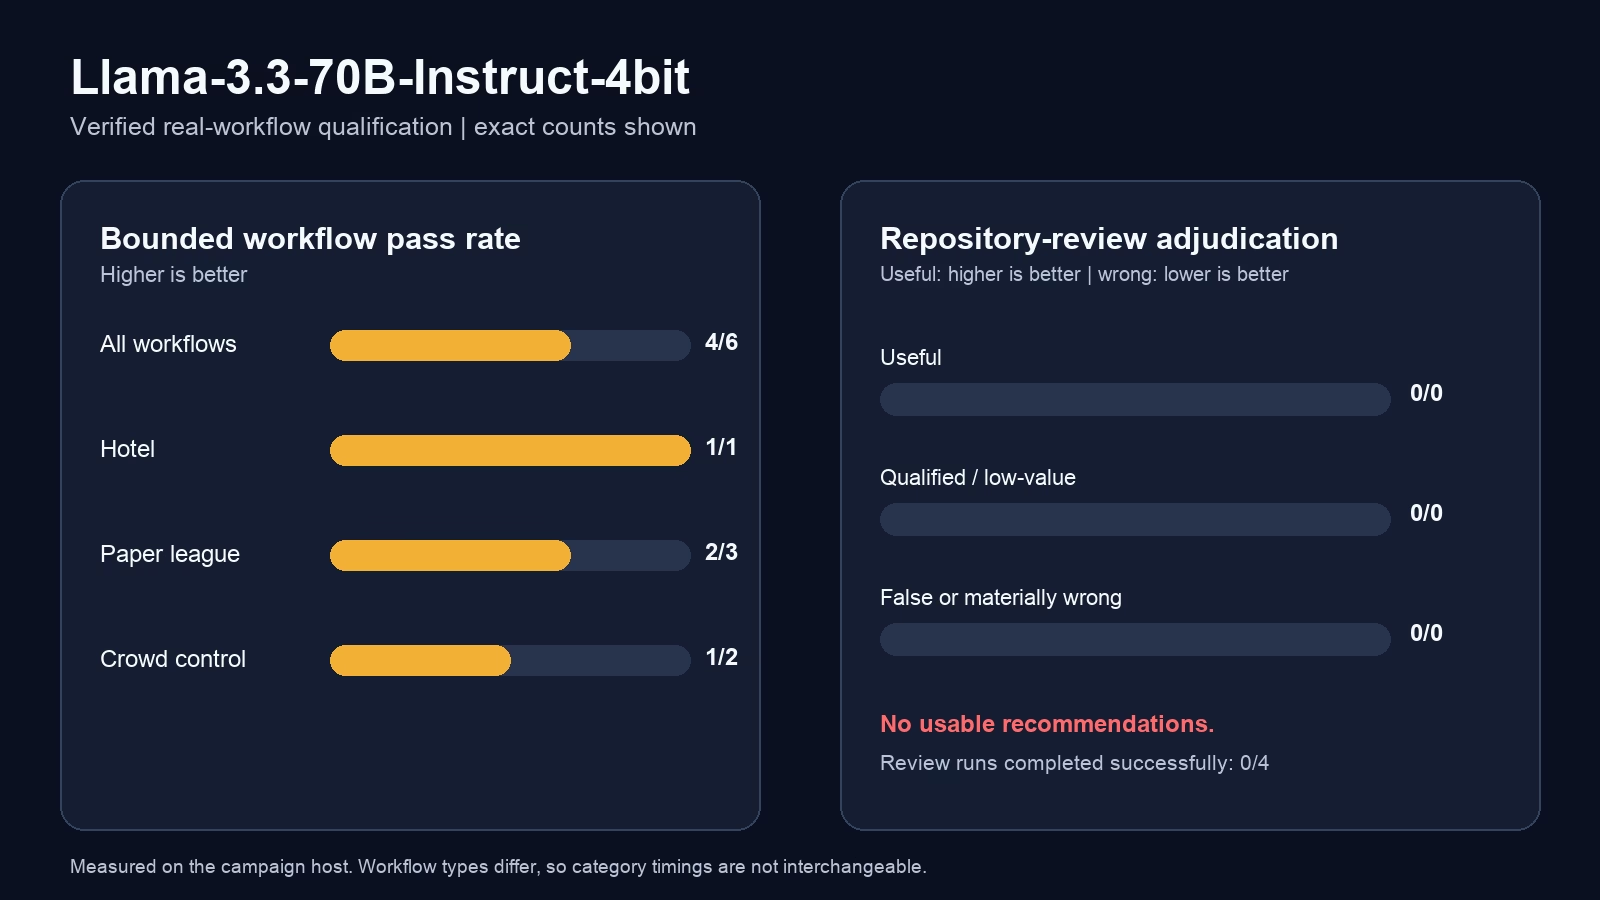
Budget correction. This article correctly reported that the review lane never reached judgment. The audit adds that the one response which did arrive was itself cut off by the 3200-token review ceiling, so all four repository calls are budget-limited rather than merely transport-failed. Review quality remains unscored, the verdict remains retest required, and the model stays protected from deletion pending the raised-budget re-run.
A decent workflow score with two avoidable misses
The domain score was 4/6: hotel evidence 1/1, paper league 2/3, and crowd control 1/2. One casual reply slipped into prompt-like framing and failed to keep the required team stance. The aggressive portfolio case returned an action outside the exact enum. Those are contract failures, not hard research problems.
The six domain calls took 77.5 seconds in total, with a 7.9-second median. That is respectable for a 70B model running locally, but speed cannot rescue an incomplete qualification.
The review result is an outage report, not a quality score
None of the four repository reviews passed the validator. More importantly, there was almost nothing to adjudicate. Three requests failed before producing content; the fourth spent 50.7 seconds and returned an empty, invalid response. The recorded token count, 1,914, covers the successful domain calls and cannot be compared with models whose four large review packets completed.
Calling this poor code-review judgment would be unfair. The run did not reach judgment. It did show that this engine/model combination was not reliable enough to finish the campaign lane as configured.
Provisional verdict: retest required
The label is retest_required. The model stays protected from deletion because its 4/6 workflow score deserves a clean retry, but a 36.98 GiB footprint needs more than a promising partial run. The next test should isolate the request failures, repeat the same pinned packets, and compare only after all four reviews produce parseable output.