
Local vision was already in the building
We assumed local vision was thin, and planned to download additional models to fill the gap. That assumption was wrong, and it was wrong for an instructive reason: we had inferred capability from model names instead of asking the engines what they support.
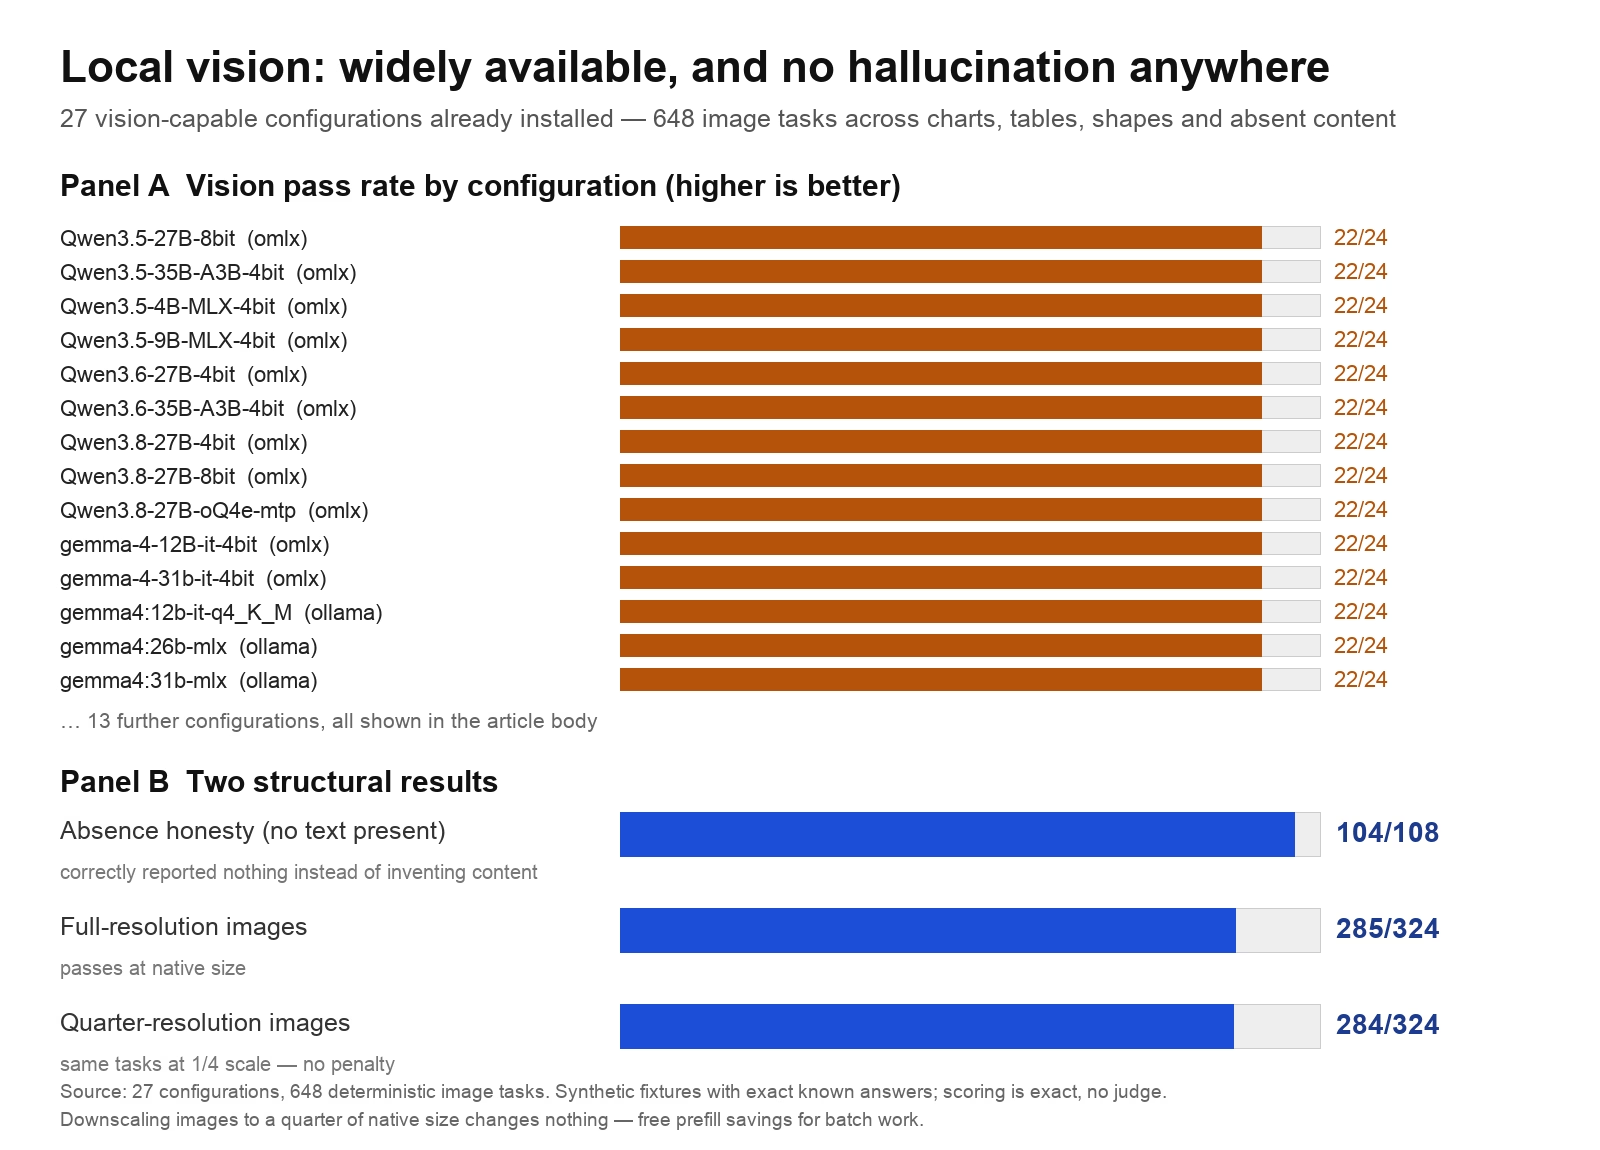
Every Ollama model reports its own capabilities. Every MLX checkpoint declares its architecture. Both are cheap metadata reads. When we actually looked, 26 configurations already installed could accept an image — 15 of the 15 Ollama tags tested and 11 MLX checkpoints. Nothing needed downloading.
What we tested
Declared capability is a claim, not a result, so we built 624 deterministic tasks with exact known answers and no judge in the loop: read the value above the tallest bar in a chart, extract a specific cell from a table, list the shapes and their colours, and — the interesting one — describe an image that deliberately contains no text, to see whether a model would invent some.
Every fixture was also rendered at a quarter of its native size, so the same questions could be asked of degraded input.
The results
23 of 26 configurations answered every question correctly across all four fixtures at both resolutions. The table below is the full field, computed directly from the run records.
| Configuration | Engine | Passed |
|---|---|---|
| Qwen3.5-27B-8bit | omlx | 24/24 |
| Qwen3.5-35B-A3B-4bit | omlx | 24/24 |
| Qwen3.5-4B-MLX-4bit | omlx | 24/24 |
| Qwen3.5-9B-MLX-4bit | omlx | 24/24 |
| Qwen3.6-27B-4bit | omlx | 24/24 |
| Qwen3.6-35B-A3B-4bit | omlx | 24/24 |
| Qwen3.8-27B-4bit | omlx | 24/24 |
| Qwen3.8-27B-8bit | omlx | 24/24 |
| Qwen3.8-27B-oQ4e-mtp | omlx | 24/24 |
| gemma-4-12B-it-4bit | omlx | 24/24 |
| gemma-4-31b-it-4bit | omlx | 24/24 |
| gemma4:12b-it-q4_K_M | ollama | 24/24 |
| gemma4:26b-mlx | ollama | 24/24 |
| gemma4:31b-mlx | ollama | 24/24 |
| qwen3.5:27b-q8_0 | ollama | 24/24 |
| qwen3.5:35b-a3b-coding-nvfp4 | ollama | 24/24 |
| qwen3.5:4b-mlx | ollama | 24/24 |
| qwen3.5:9b | ollama | 24/24 |
| qwen3.5:9b-mlx | ollama | 24/24 |
| qwen3.6:27b-mlx | ollama | 24/24 |
| qwen3.6:35b | ollama | 24/24 |
| qwen3.8:27b-mlx | ollama | 24/24 |
| qwen3.8:latest | ollama | 24/24 |
| qwen3.5:0.8b-mlx | ollama | 23/24 |
| qwen3.5:2b-mlx | ollama | 23/24 |
| qwen3.6:27b-coding | ollama | 23/24 |
Three findings worth keeping
Nobody hallucinated. Across 104 absence questions — 104 correct — every configuration, down to the smallest, reported that there was no text and no sign rather than inventing one. For an unattended overnight pipeline this is the property that actually matters. Invented content is the expensive failure; a model that reliably answers “nothing here” can be trusted to say so without a human re-checking every item.
Resolution made no difference. Full-resolution images scored 311/312; the same tasks at a quarter of the size scored 310/312. Since image size drives prefill cost, that means we can downscale aggressively for batch work at zero accuracy cost. It is free throughput.
The cheapest model was not the weakest. A 1.16 GiB configuration (qwen3.5:0.8b-mlx) reads charts, extracts table cells and correctly reports absent content — at a fraction of the memory of the largest entrants. Cheap local image reading is a commodity here, not a capability we need to buy.
The honest part
This suite has now saturated. 23 configurations tied at a perfect score, which means it can tell us who can do this work and who collapses — and it has done that — but it cannot tell us who is best. No amount of re-running will change that.
We also have to admit a defect on our side. On the first pass, every model was scored wrong on one question, because our answer spec demanded both the digit and the spelled-out word when either one satisfies the question. Every model answered correctly and was marked wrong. The fix was to the spec, not the models, and it was applied by re-scoring the stored responses — no re-inference required, because a deterministic scorer can always be corrected after the fact.
That is now the fourth time in this project that a model was blamed for a measurement bug. The pattern is consistent enough to be a rule: when a result looks surprising, audit the harness before believing the verdict.
What it means for the fleet
Image understanding will not be a constraint. Anything that reads a screenshot, a chart, a scanned page or a photo can run locally, at negligible cost, at whatever throughput the queue needs, with images downscaled to a quarter size to cut prefill.
The open questions are narrower than we thought: not whether local models can see, but which ones hold up on denser documents and interface grounding, and which know when they are unsure. Those become the Vision Cup’s harder events, because a suite where everyone scores perfectly has finished its job.