Chance Rates in Disguise: When a Benchmark Quietly Measures Nothing
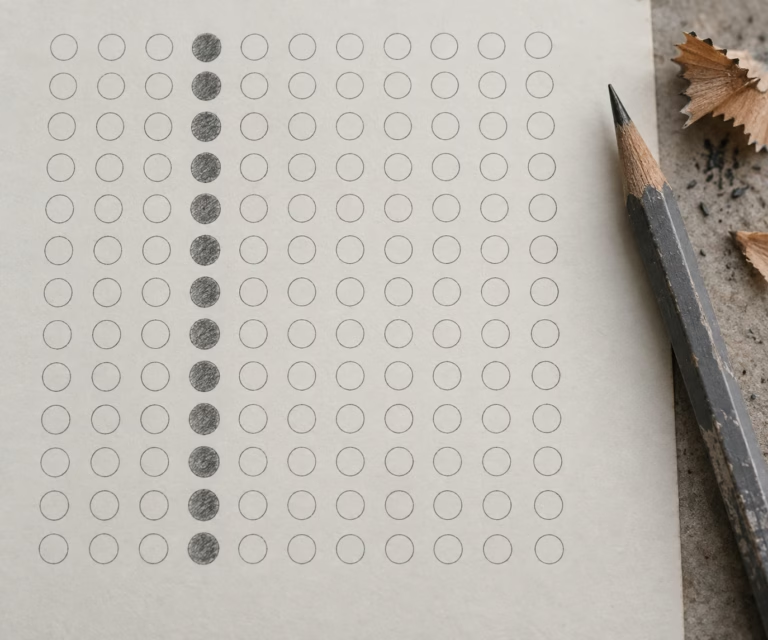
One of our models scored 0.235 on MMLU. For a 32B reasoning model, that is chance. It looked like a finding about the model. It was a finding about our harness. A single column filled in while every other option stays blank — the shape of an extractor vote. Original editorial image by Aura for…